Standard versus Deep Evidence: How to Choose the Context Budget
Standard mode uses 8,192 evidence tokens; Deep uses 24,000. These are source budgets, not model context windows or the R454 7,000-token research budget. Screenshots were captured on 0.7.13.
By Neeraj Yadav. MemStrata is built by Neeraj Yadav.
Two named modes, illustrated in historical screenshots
In the installed Assistant, Evidence mode offers Standard 8k and Deep 24k. Both use the same index. You connect your own AI. Switching mode does not require re-embedding.
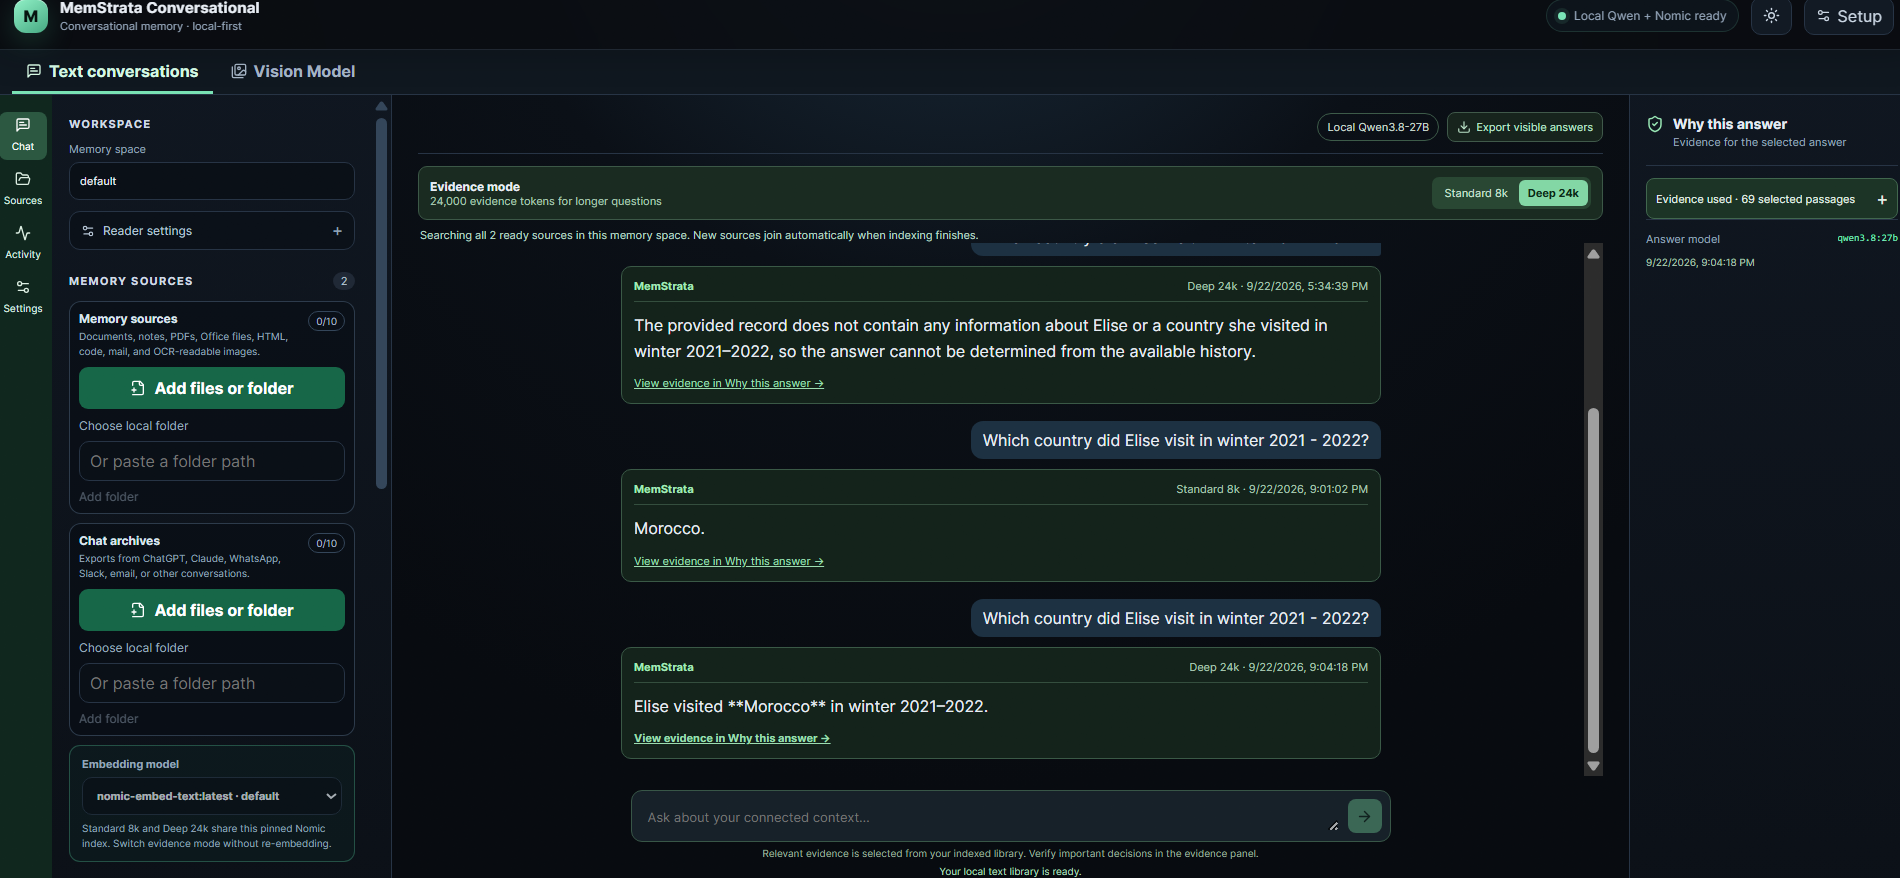
| Mode | Evidence limit | When to use it |
|---|---|---|
| Standard | 8,192 tokens | Default for most questions |
| Deep | 24,000 tokens | When Standard evidence is not enough |
Evidence tokens are the retrieved-source budget. They do not include system instructions, the question, later conversation, or output capacity.
Research budgets are a different setting
The R454 and R230 research runs used a 7,000-token evidence budget. That is not product Standard and not Deep. Tokenizer and counting conventions live on the evaluation methods page. Do not relabel 7,000 as 8,192.
What this page does not claim
This page does not report measured latency or accuracy on named hardware for Standard versus Deep. A larger evidence budget can include more source text. It is not an accuracy SLA. If Standard evidence is empty or obviously incomplete, inspect Why this answer before switching to Deep.
Hardware and model notes: Platform and model notes.
Previous: Local AI Memory: What Stays on Your Device and What Goes to a Model Provider